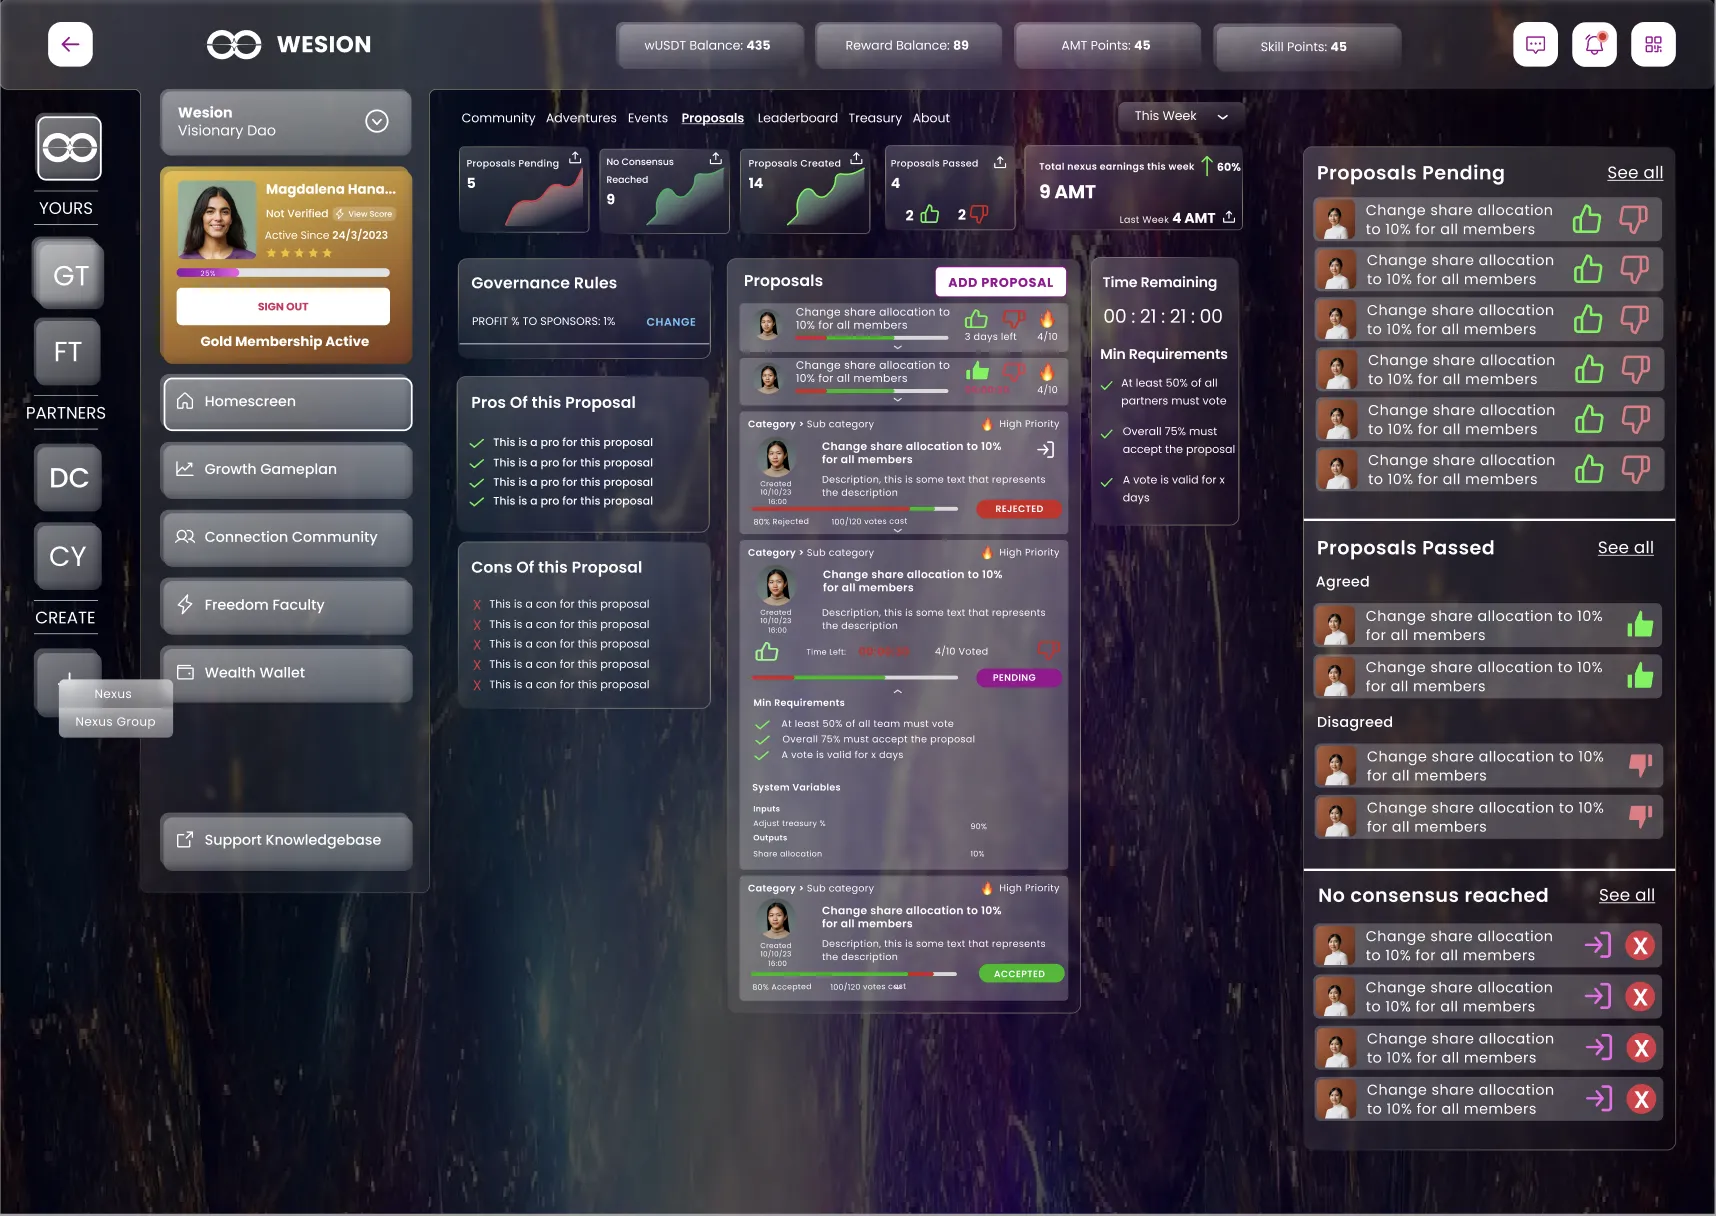
Wesion (Abundance Movement) · AI integration
AI matching and recommendations at 5% of the cost
- lower LLM spend
- 95%lower LLM spend
- AI services in production
- 11AI services in production
AI integration
I add AI features to real products — matching, recommendations, summarisation and search — and keep the bill under control. On one platform I cut LLM spend by 95% without losing output quality.
Is this you?
What you get
OpenAI GPT and LangChain features wired into your back end with prompt versioning, guardrails, retries and logging.
Embeddings and vector databases such as Pinecone for recommendations, matching and retrieval-augmented generation (RAG).
Model selection, token limits and per-feature cost tracking so every AI feature has a known price per user.
Scheduled jobs that summarise conversations, classify content and generate reports from your data.
Proof
Wesion (Abundance Movement) · AI integration
Helpicon · Full-stack web development
FAQ
Mostly OpenAI's GPT models through the API, orchestrated with LangChain, and vector databases such as Pinecone. I pick the cheapest model that meets the quality bar for each feature.
By measuring each feature separately, moving tasks that did not need a reasoning model to a smaller one, limiting tokens per use case and tuning temperature — then checking output quality against the old results.
Yes. AI features are usually a new service or module beside your current back end, so they can be added without a rewrite.
Data sent through the OpenAI API is not used to train their models by default. I also keep personal data out of prompts where it is not needed.
Tell me what you are building and where it hurts, and I will come back with questions or a plan.